The first launch of MAPLE.
MAPLE
Launched Nov 10, 2026Prunes Gemma 4 26B to run fully on a 6 GB GPU
Meet the team
Hunted by Ilyas. The makers are not on 25launches yet.
 H (Hunter)
Prunes Gemma 4 26B to run fully on a 6 GB GPU
0 followers
Artificial IntelligenceOpen Source
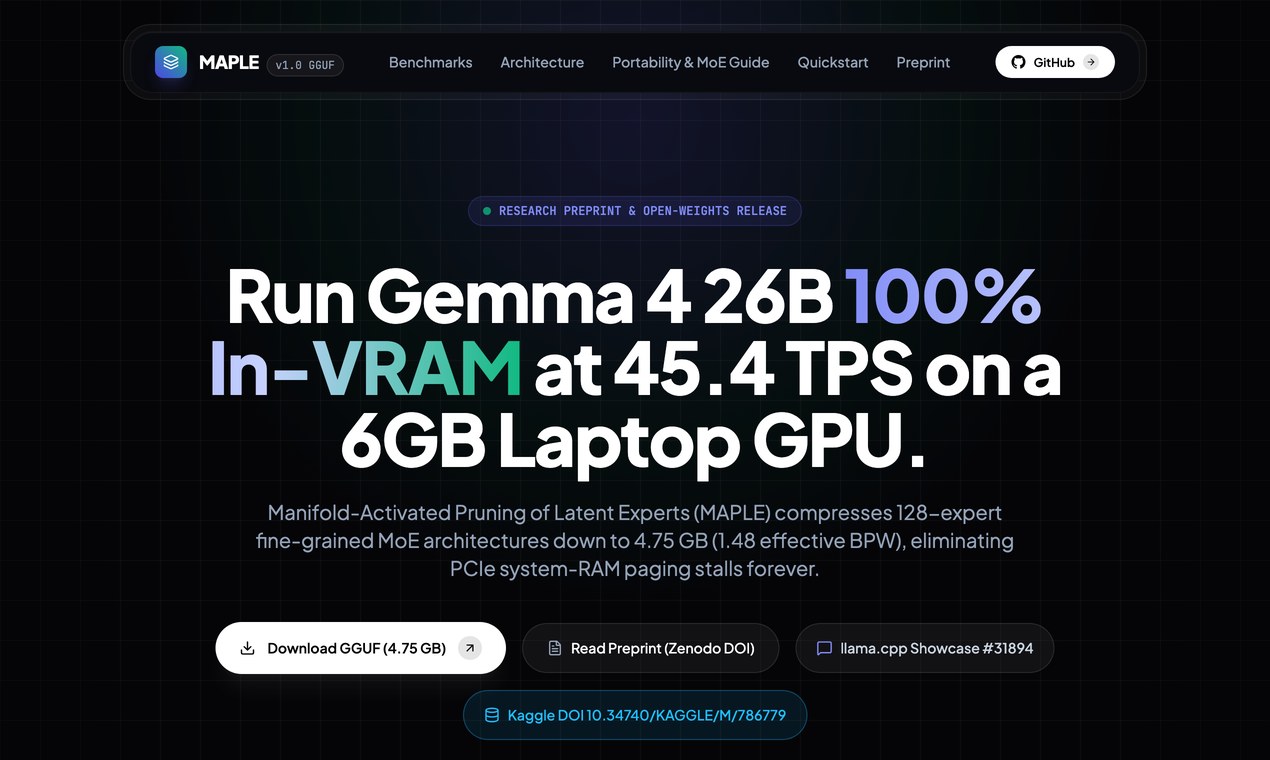
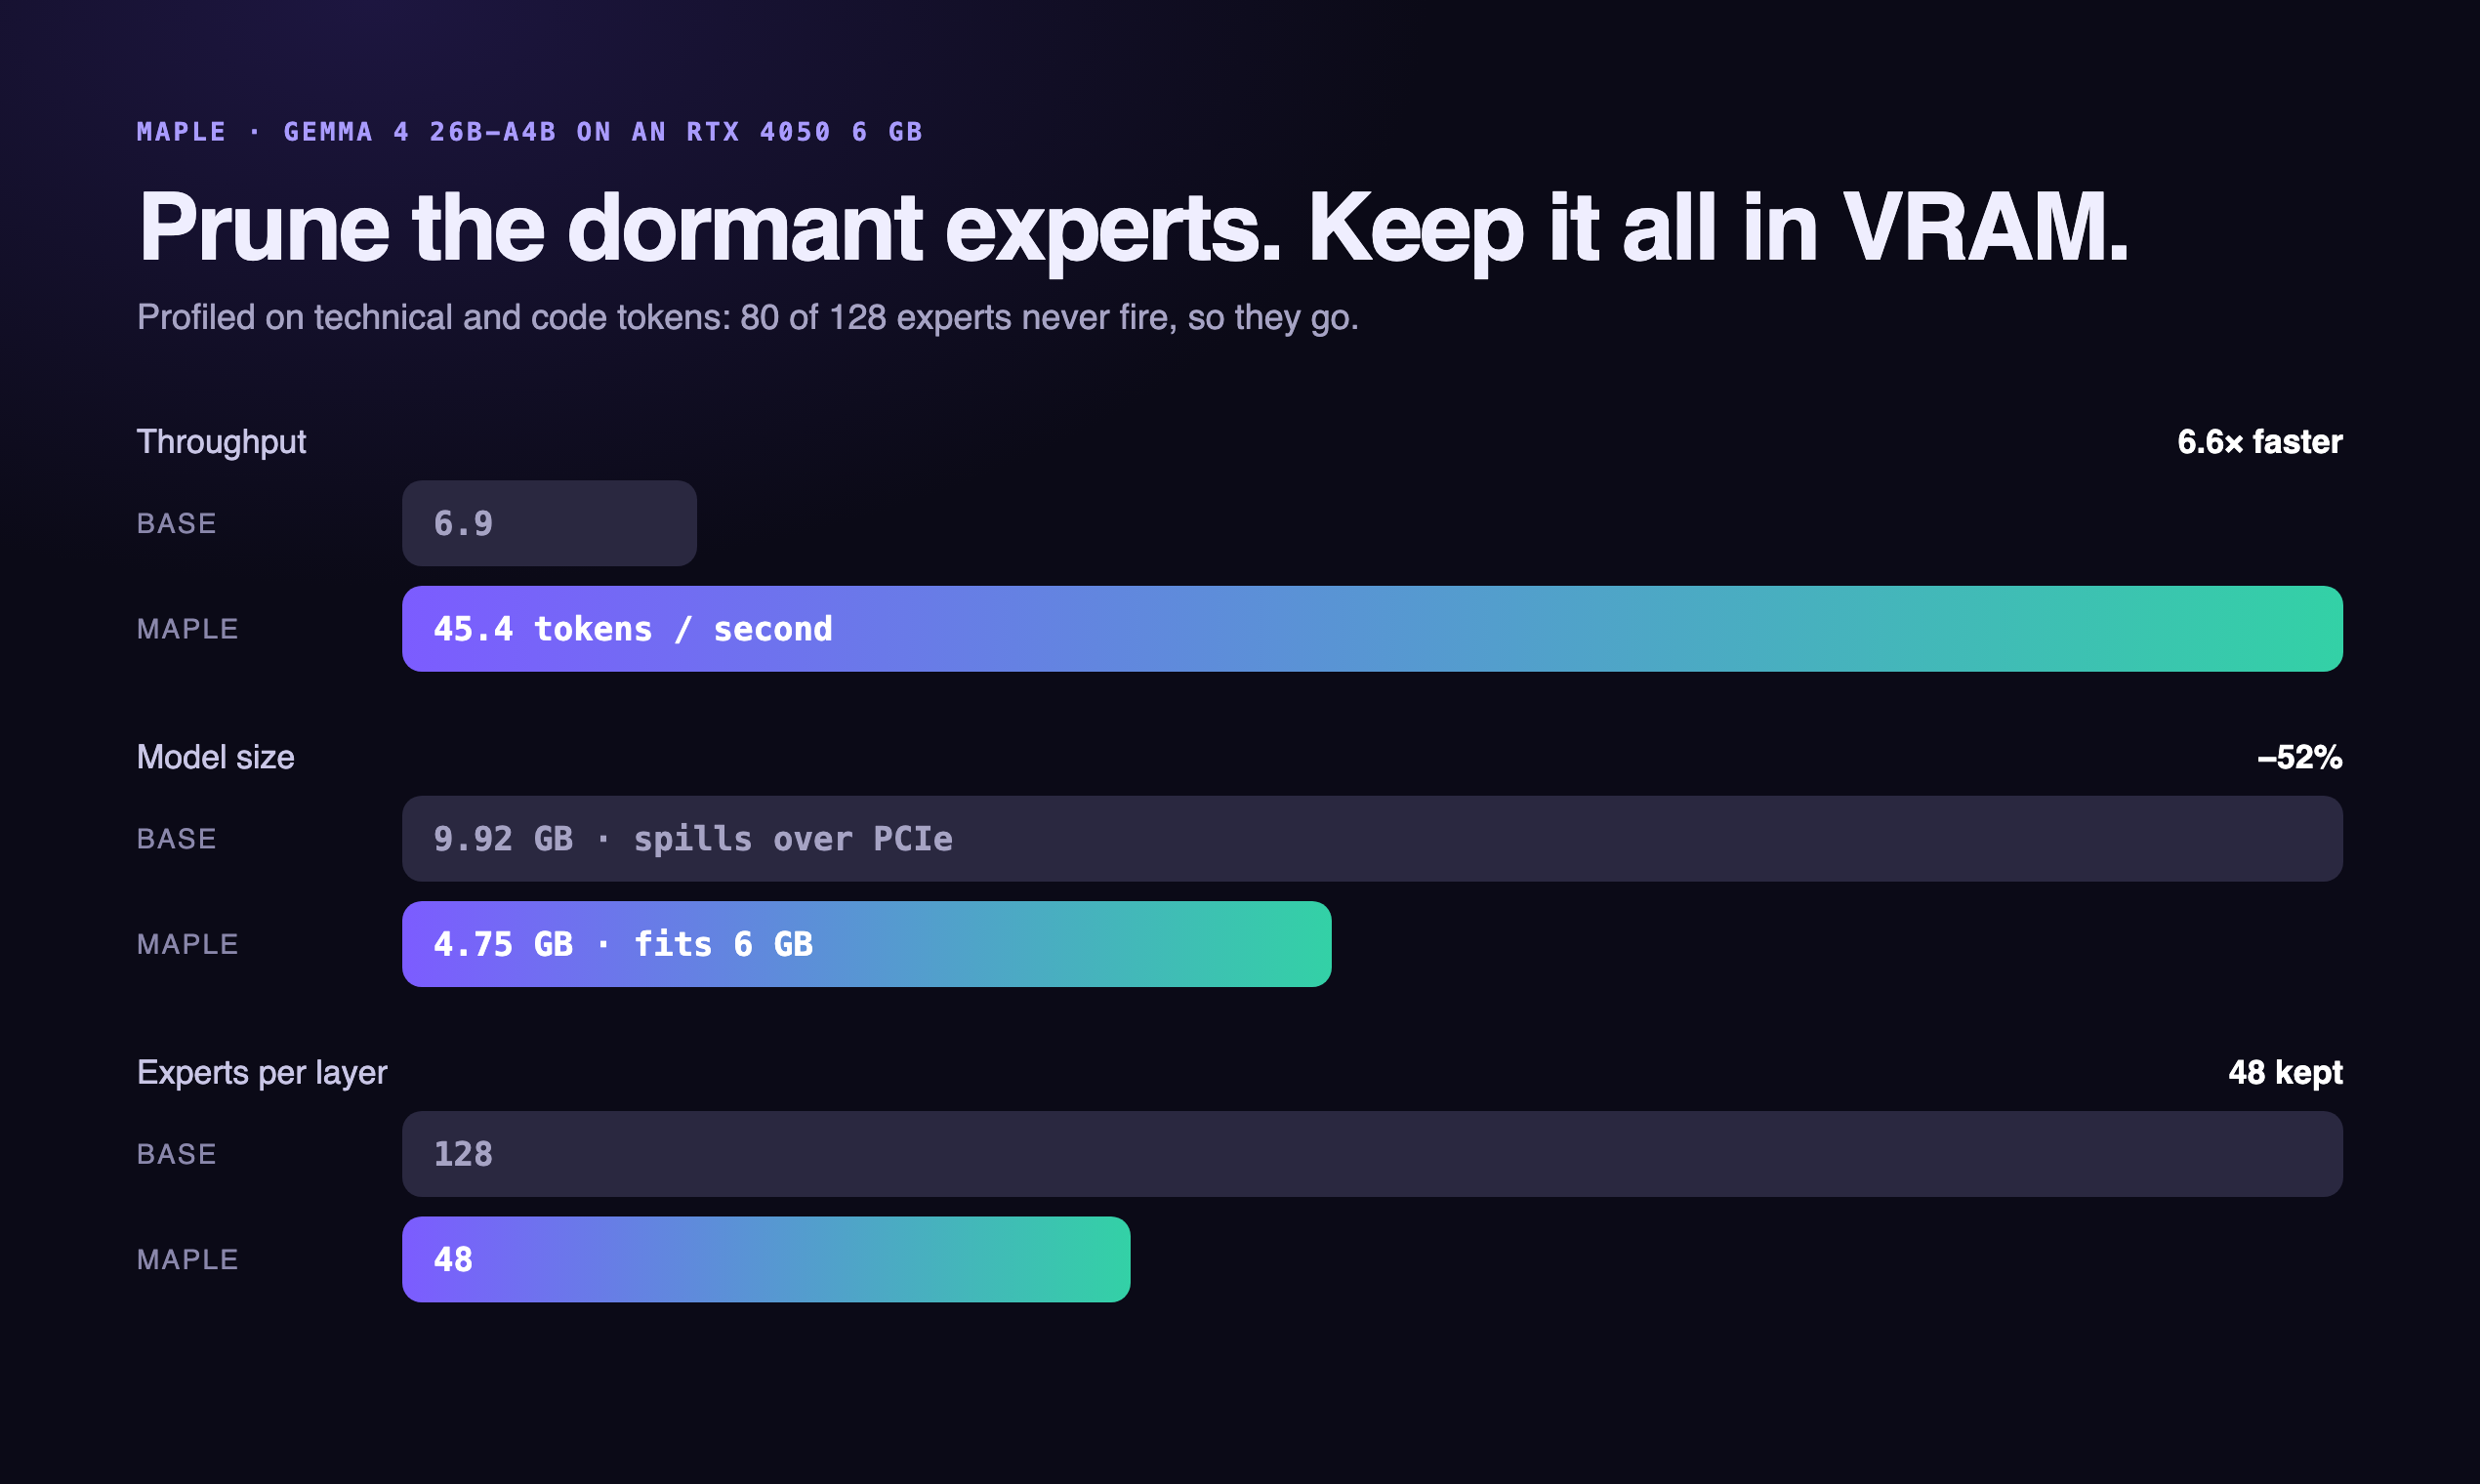
MAPLE compresses mixture-of-experts LLMs by removing rarely used experts. On Gemma 4 26B-A4B it keeps 48 of 128 experts per layer, chosen from activation profiles on technical text, and shrinks the GGUF from 9.9 GB to 4.75 GB, so the model fits entirely on a 6 GB laptop GPU. The author reports 45 tokens/s instead of 6.9 with partial CPU offload, on his own small benchmarks. Apache-2.0.
The first launch of MAPLE.
Prunes Gemma 4 26B to run fully on a 6 GB GPU
Hunted by Ilyas. The makers are not on 25launches yet.
H (Hunter)