25launches

The first launch of MAPLE.

MAPLE page

MAPLE

Launched Nov 10, 2026

Prunes Gemma 4 26B to run fully on a 6 GB GPU

Hunted by IlyasHunter
Visit github.com (opens in a new tab)

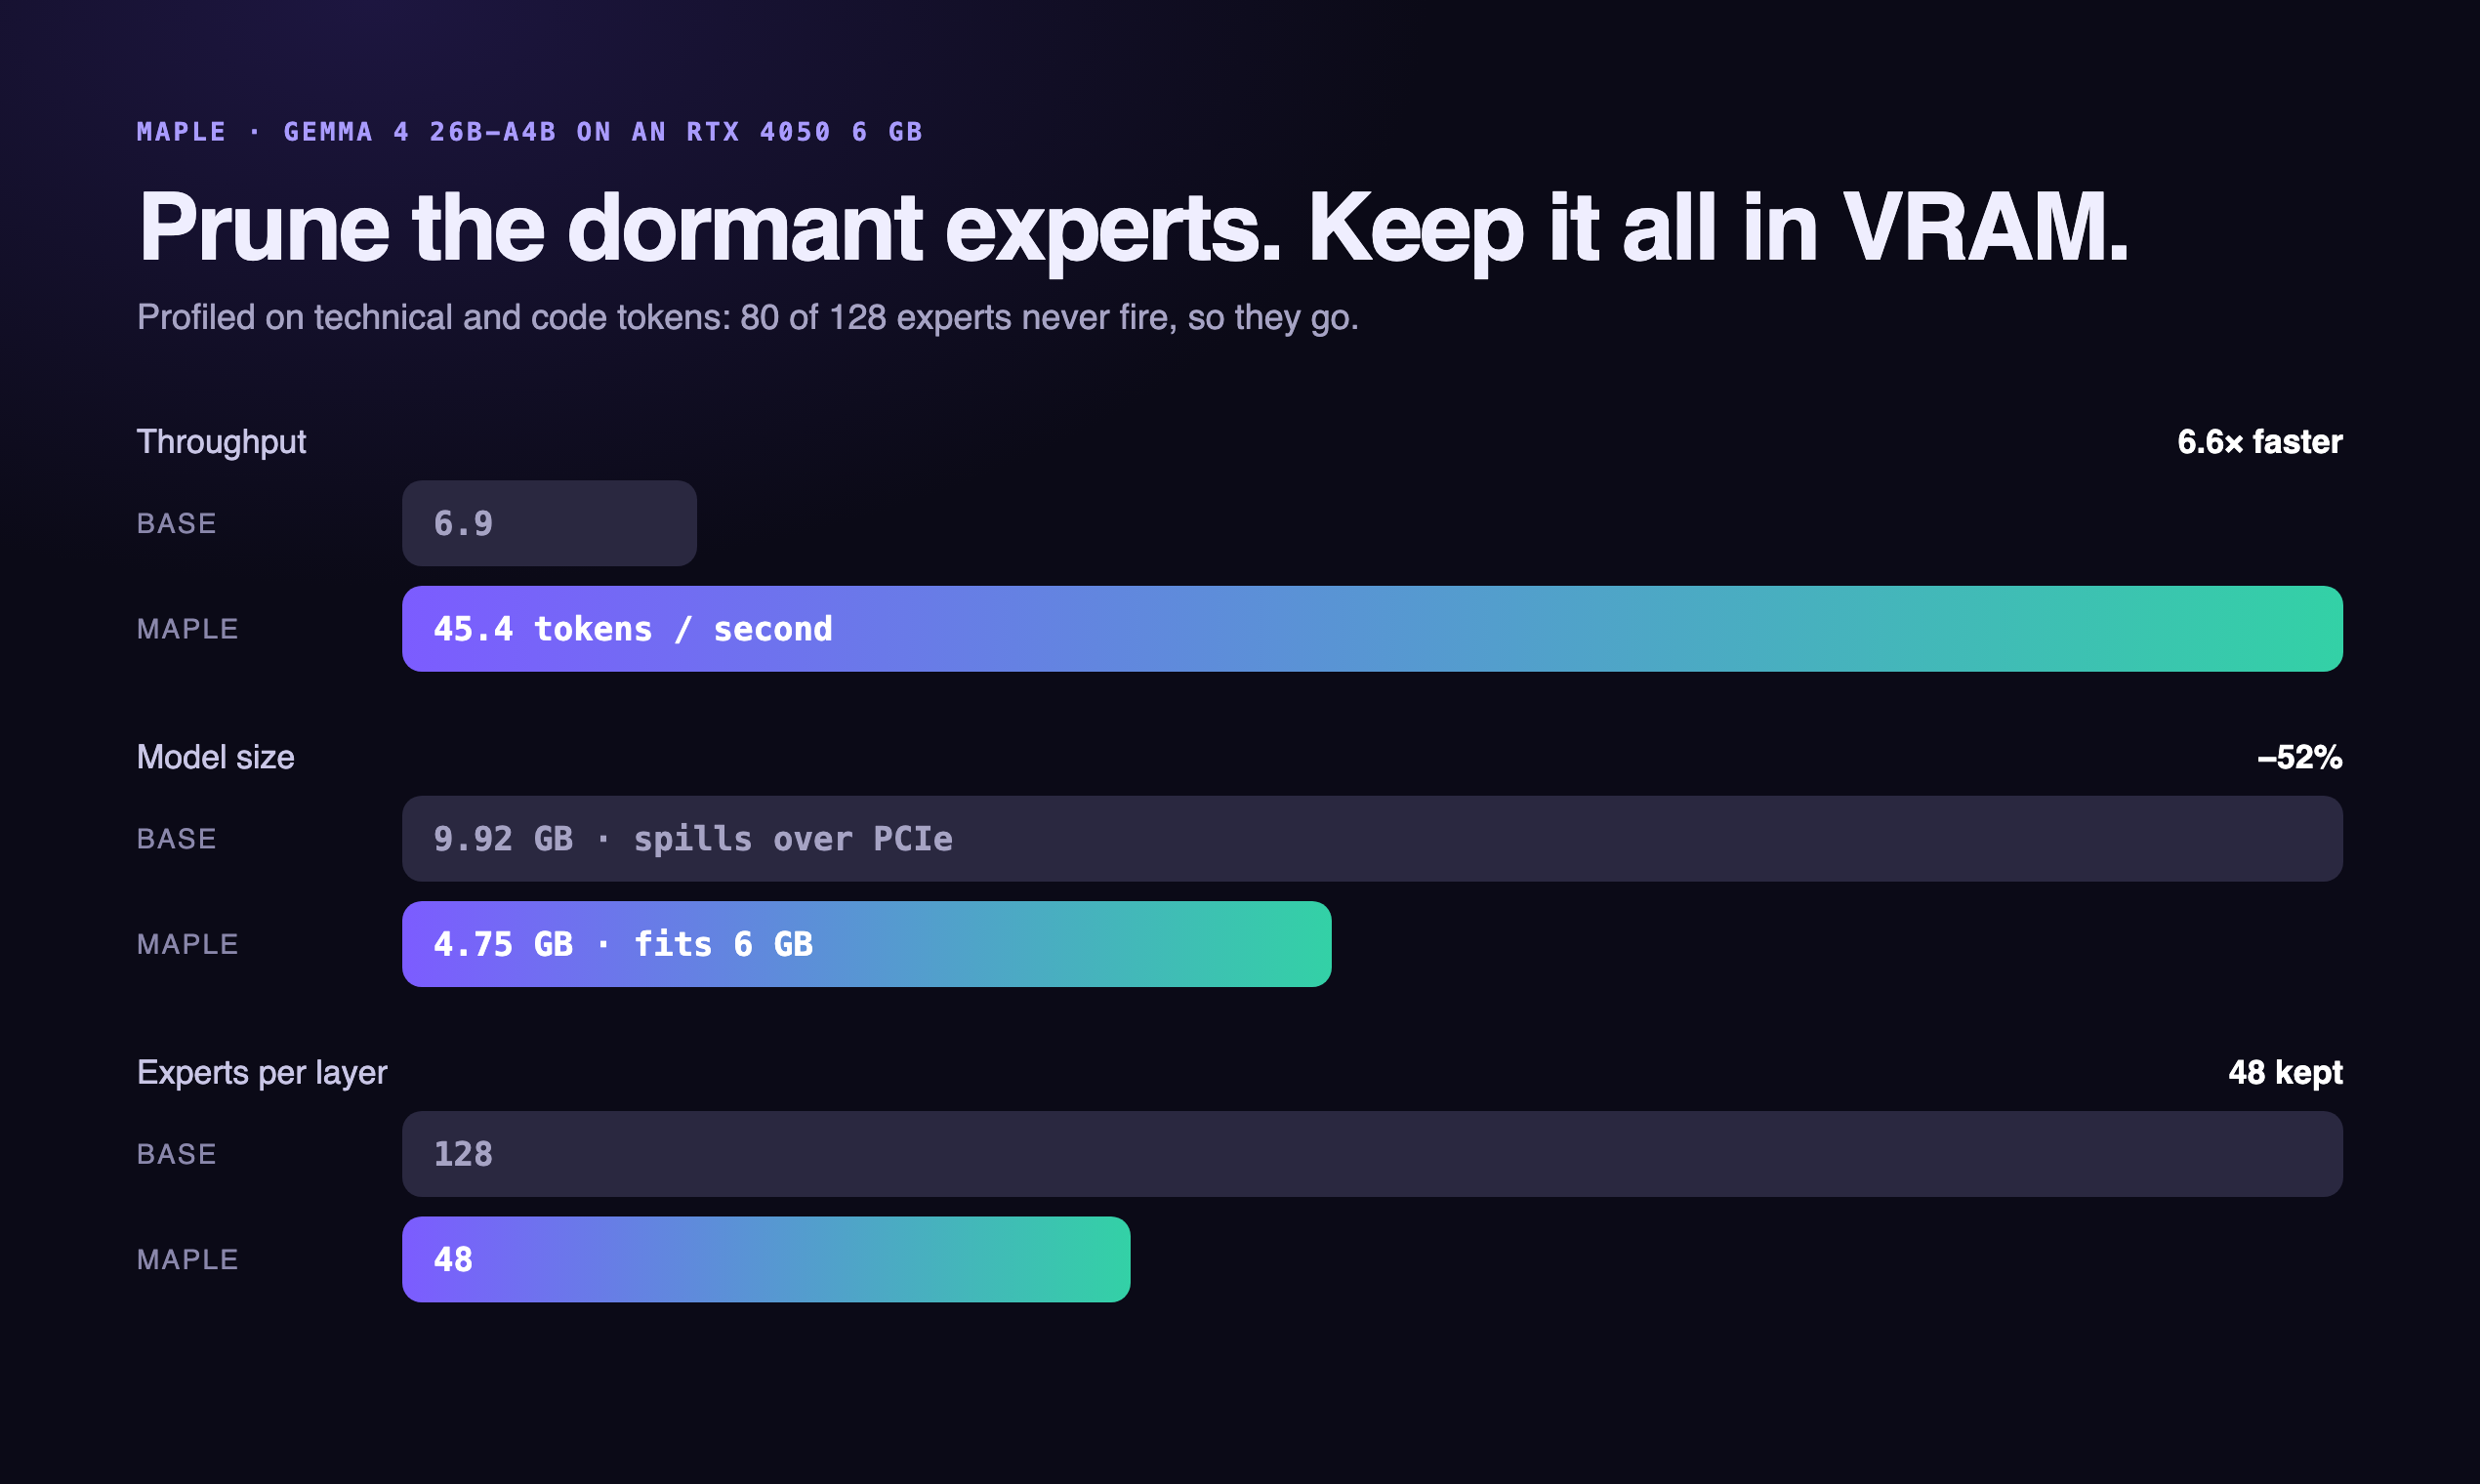
MAPLE compresses mixture-of-experts LLMs by removing rarely used experts. On Gemma 4 26B-A4B it keeps 48 of 128 experts per layer, chosen from activation profiles on technical text, and shrinks the GGUF from 9.9 GB to 4.75 GB, so the model fits entirely on a 6 GB laptop GPU. The author reports 45 tokens/s instead of 6.9 with partial CPU offload, on his own small benchmarks. Apache-2.0.

▲ 0 upvotes

Meet the team

Hunted by Ilyas. The makers are not on 25launches yet.
H (Hunter)
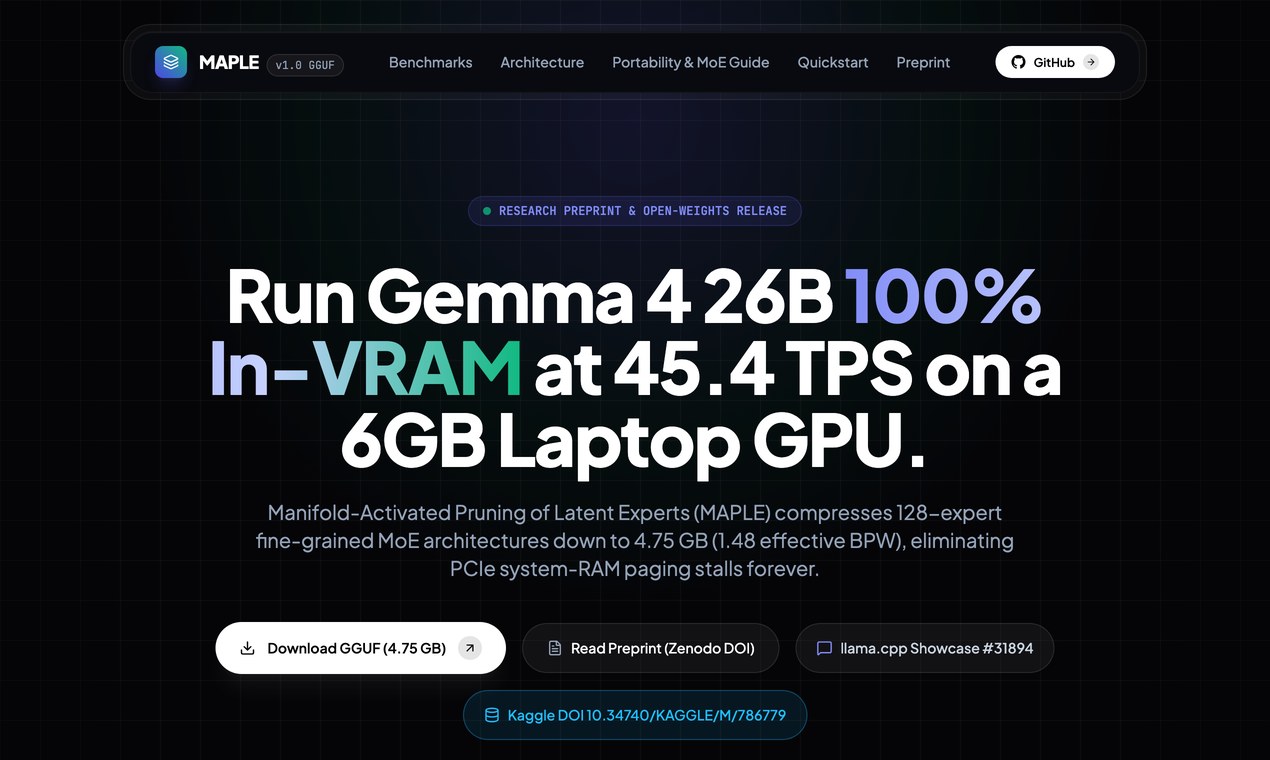
  • MAPLE screenshot 1
  • MAPLE screenshot 2

Discussion 1

Ask questions, give feedback. Comments don't count in the ranking.

Sign in to join the discussion.

  • IlyasHunter Pinned

    Local inference keeps getting better on small GPUs. MAPLE prunes the experts a MoE model rarely uses for your kind of work. The headline speedup mostly comes from no longer offloading to CPU, and quality outside technical text drops, but it's a clever trade-off to try.