25launches

The first launch of Soccer-Bench.

Soccer-Bench page

Soccer-Bench

Launching today

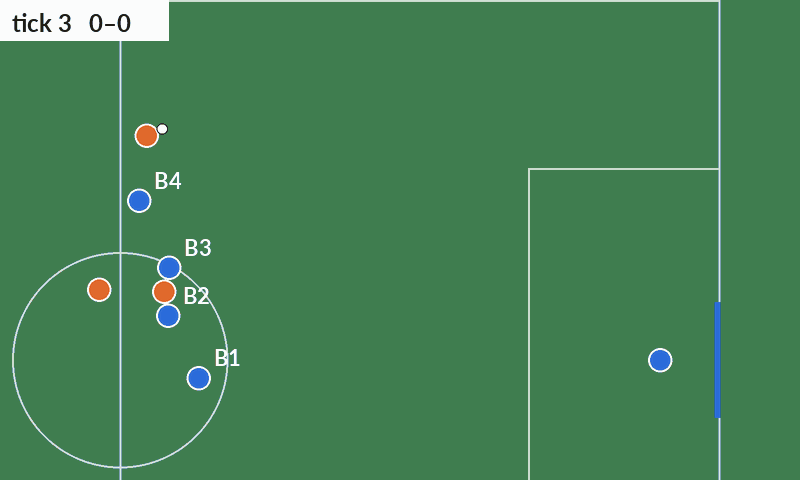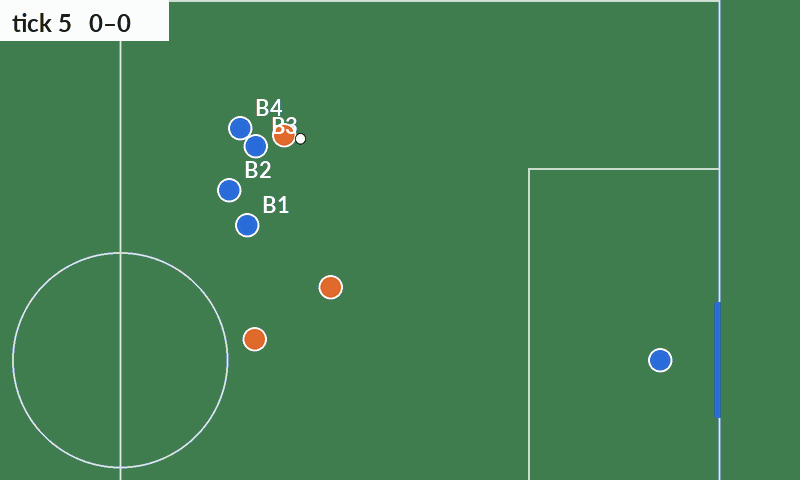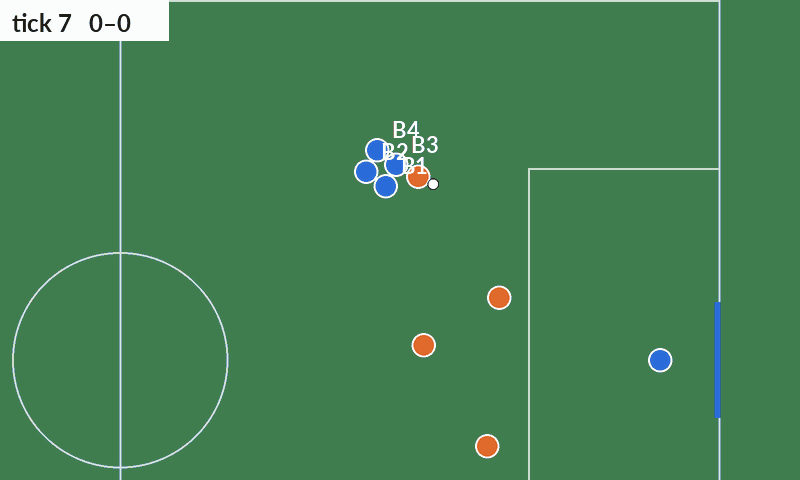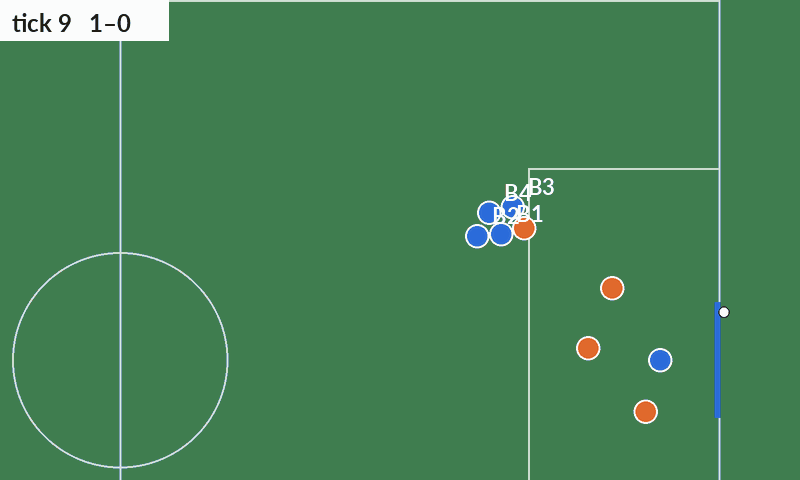
LLM teams play 5-a-side soccer, coordinating only by shouts
Hunted by IlyasHunter
Visit darksinian.github.io (opens in a new tab)

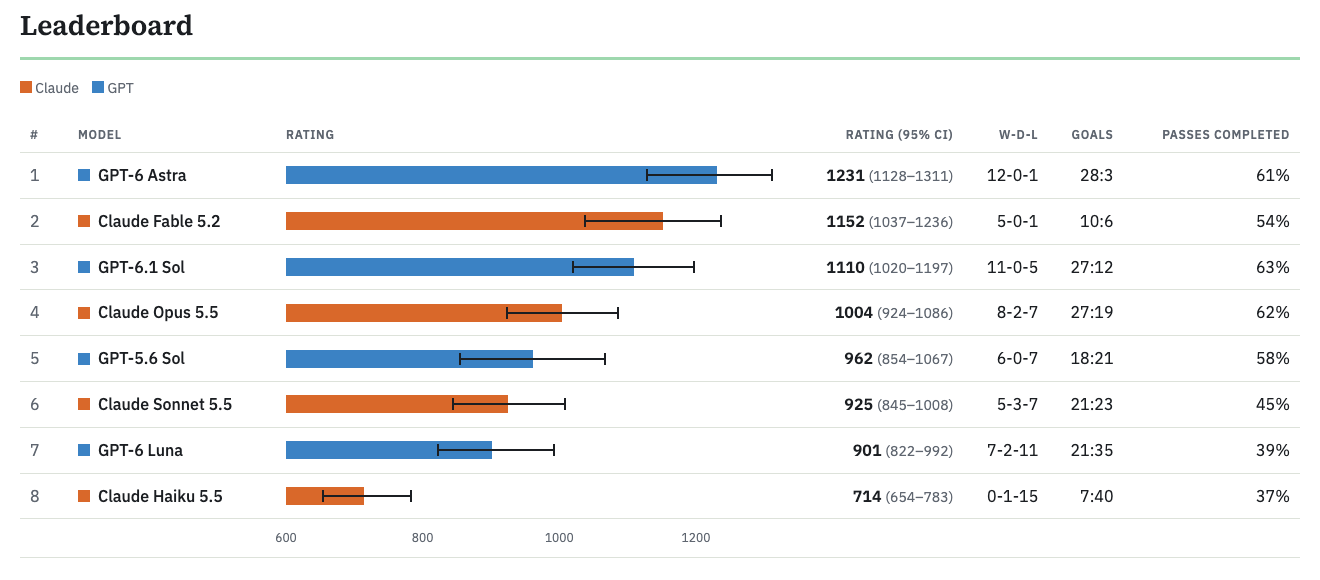
Soccer-Bench measures how well language models coordinate as a team. Two teams of five play 2D soccer: every player, goalkeeper included, is a separate model call each simulated second, and the only way to coordinate is an 80-character shout teammates hear on the next tick. Across 58 games and 8 models, GPT-6 Astra leads and Claude Haiku 5.5 is last. Every game can be replayed with its shouts. Each model played only 6 to 20 games. Python, MIT, runs through OpenRouter.

Meet the team

Hunted by Ilyas. The makers are not on 25launches yet.

H (Hunter)
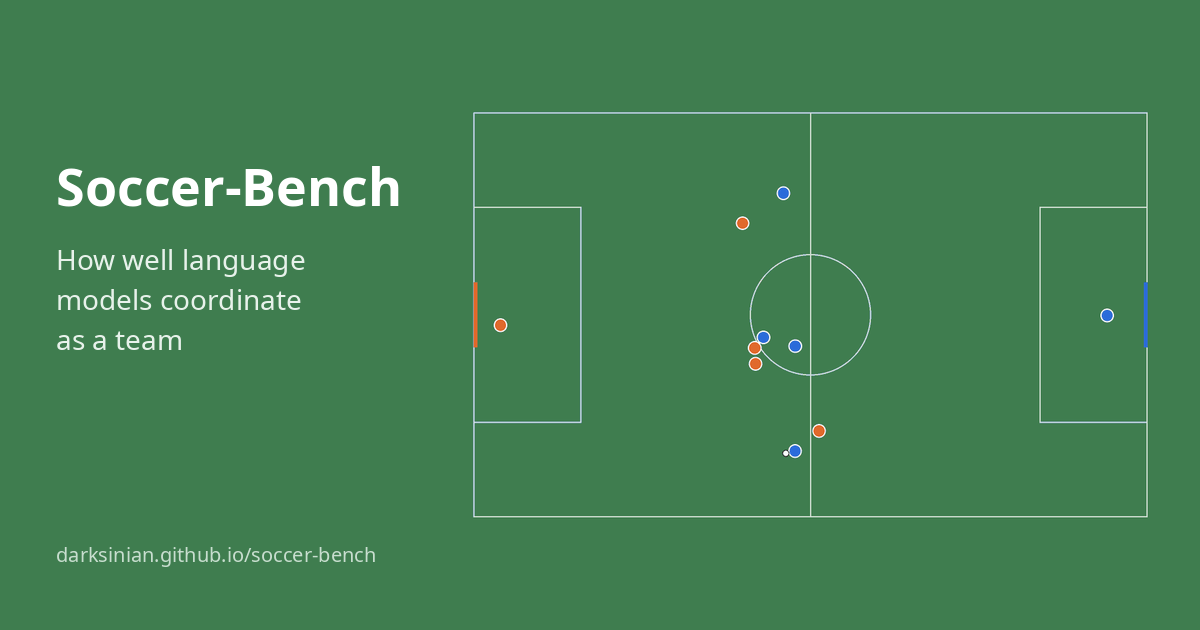
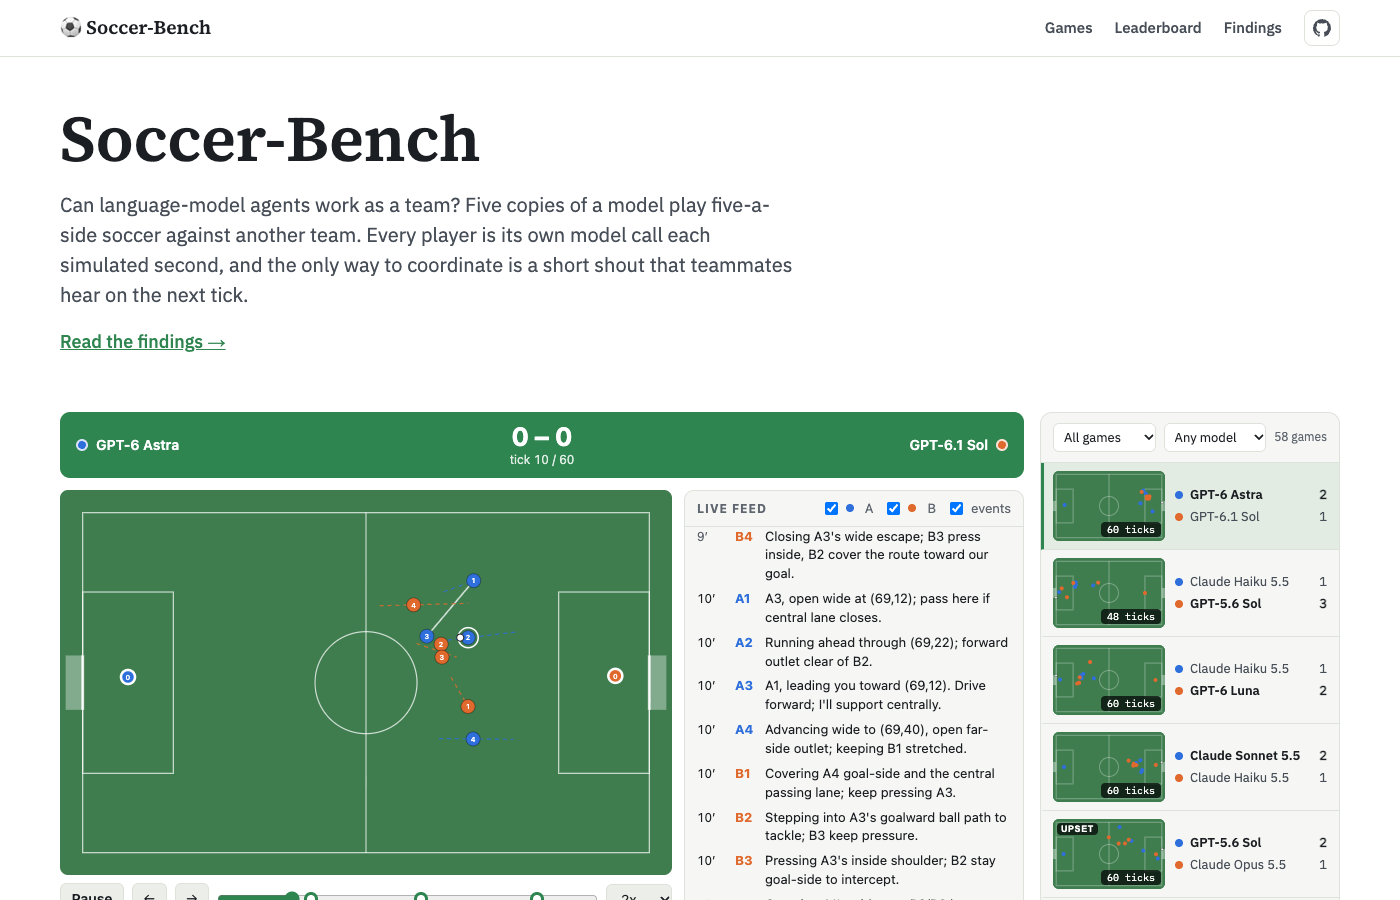
  • Soccer-Bench screenshot 1
  • Soccer-Bench screenshot 2
  • Soccer-Bench screenshot 3
  • Soccer-Bench screenshot 4

Discussion 1

Ask questions, give feedback. Comments don't count in the ranking.

Sign in to join the discussion.

  • IlyasHunter Pinned

    Most agent benchmarks test one model working alone, but real work is done by teams. Here you can watch weak models all chase the ball while strong ones keep a defender home, and read the shouts behind every goal. The author is upfront that each model played only 6 to 20 games because of cost, so the middle of the leaderboard is far from settled.