25launches

The first launch of Caramel-1.

Caramel-1 page

Caramel-1

Launching today

Open speech model that learned to talk from audio alone
Hunted by IlyasHunter
Visit github.com (opens in a new tab)

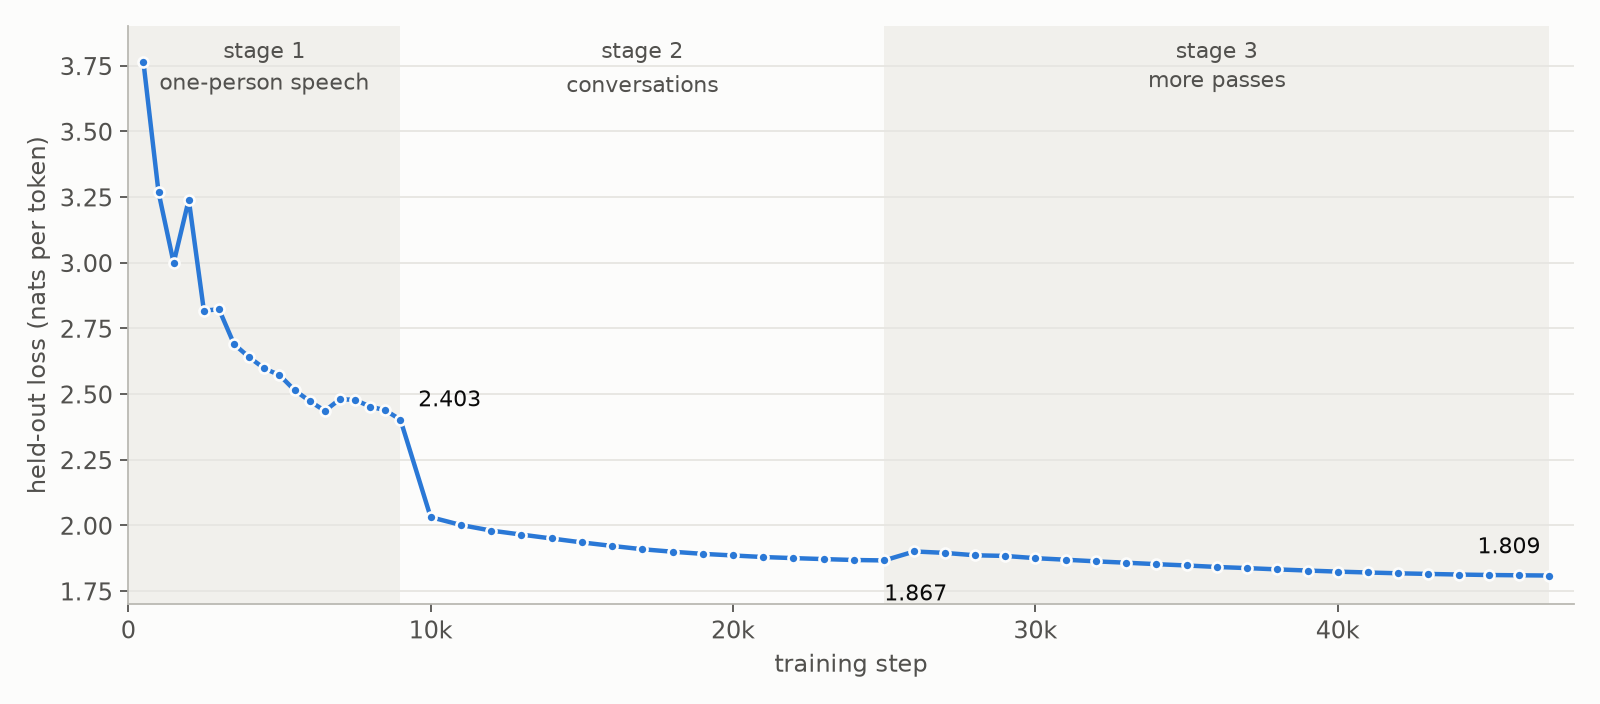
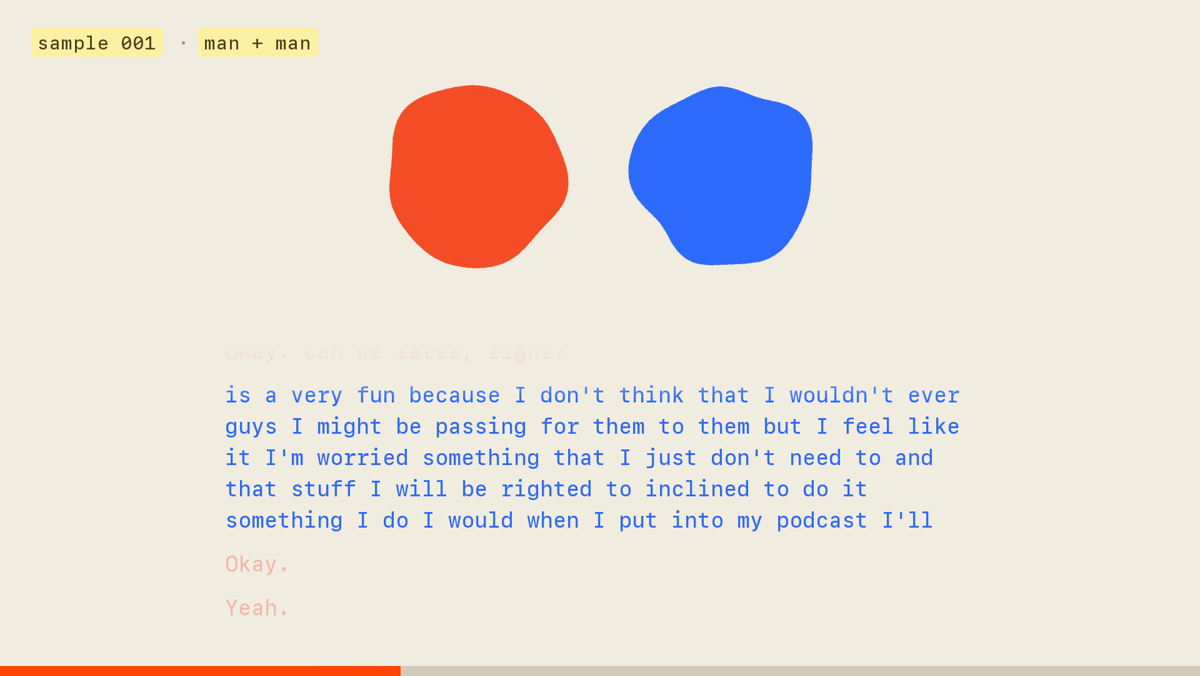
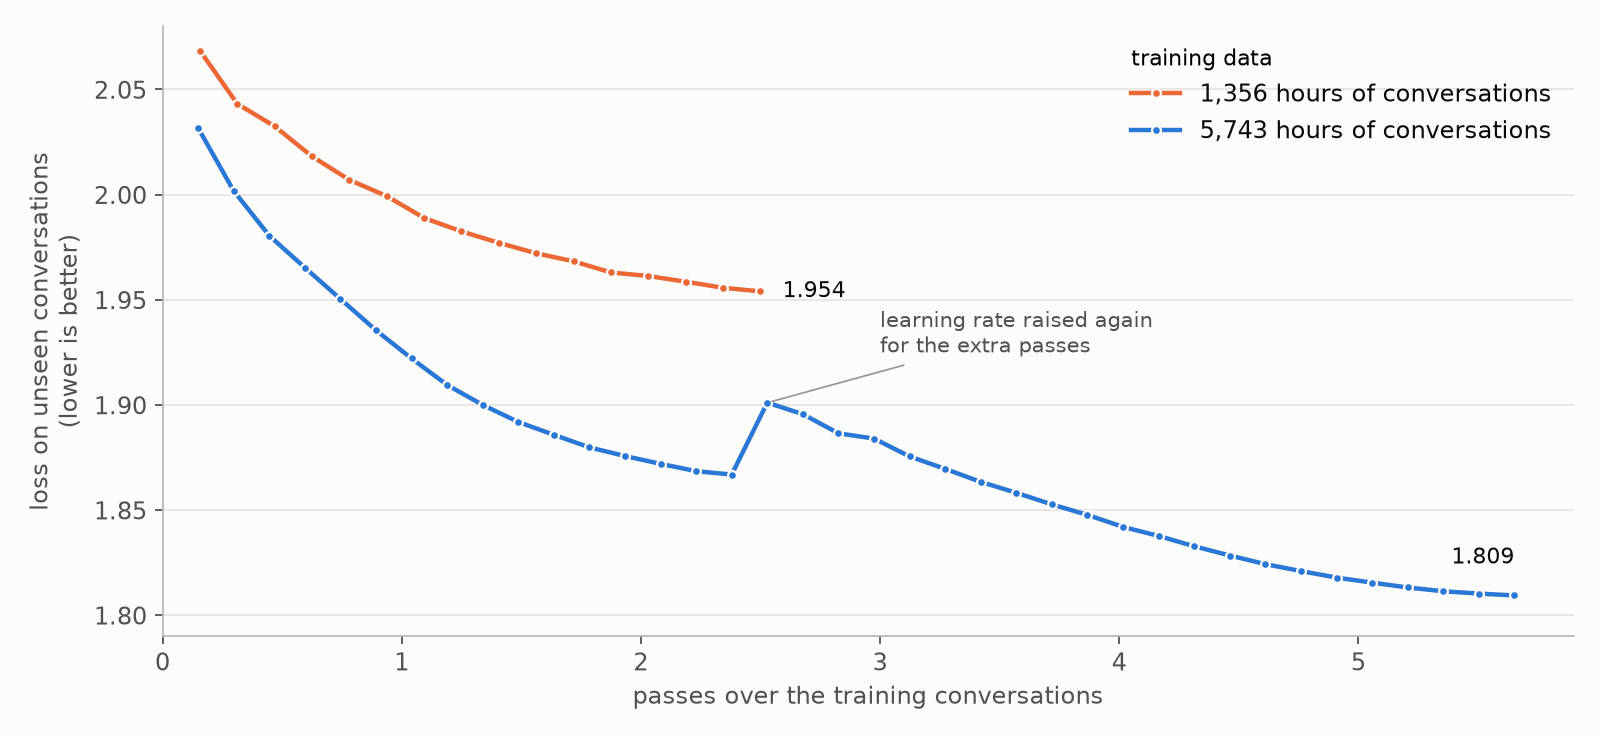
Caramel-1 is an open-source, full-duplex speech-to-speech model trained only on recordings of people talking, never on text. It has 413M parameters and hears both sides of a conversation, deciding every 80 ms whether to speak, with no turn-taking rules. It learned from about 11,500 hours of public speech in roughly 4 GPU-hours. Runs on NVIDIA GPUs, Apple Silicon or CPU. Code, recipe and weights under Apache-2.0. The voices sound human, but most of what it says does not make sense yet.

Meet the team

Hunted by Ilyas. The makers are not on 25launches yet.

H (Hunter)
  • Caramel-1 screenshot 1
  • Caramel-1 screenshot 2
  • Caramel-1 screenshot 3

Discussion 1

Ask questions, give feedback. Comments don't count in the ranking.

Sign in to join the discussion.

  • IlyasHunter Pinned

    Voice assistants still wait for you to stop, then reply, and the stiff timing gives them away. Caramel-1 learns when to talk from real two-person recordings, so the overlaps and backchannels come from the data instead of hand-written rules, and two copies can chat live on a MacBook. Honest caveat: it sounds human but most sentences are still nonsense, and it was a few-hours experiment by one person.